
I have a new post on the ICIS blog about Google Scholar that may be of interest: ICIS: Innovating Communication in Scholarship – Some additional details of my discussion w/ reporter John Bohannon for his Science story on Google Scholar. The post gives some detail about the discussions I have with John Bohannon in relation to his story that ran in Science today on Google Scholar.
Category: Misc.

Some additional details of my discussion w/ reporter John Bohannon for his Science story on Google Scholar
There is a story in today’s Science magazine on Google Scholar by John Bohannon. Entitled “Google Scholar Wins Raves, But Can It Be Trusted” the article discusses some of the pros and cons of using Google Scholar. The author of the article interviewed me on and off over a few weeks about Google Scholar because I have written multiple blog posts on how I use it. For example see:
- Mini journal club: staged phage attack of a humanizes microbiome of mouse
- Weird things coming up from automated Google Scholar searches pointing to hea1thandfitness.com
- Playing with Impact Story to look at Alt Metrics for my papers, data, etc
- Thank you Google Scholar Updates for finding me two new papers to read
- Google Scholar has search by date option – a good thing
- Thanks Google Scholar Updates for new article to read .. wish you had an #openaccess only setting
- Wow – Google Scholar “Updates” a big step forward in sifting through the scientific literature
- Playing w/ Google Scholar’s “Citations” system – some nice features but in need of a little fine tuning
And also a diverse array of posts on Twitter which I will not rehash here.
Anyway – the new article covers some interesting points but is very very short (ahh — the fun with page length restrictions). So I thought I would post here some of the comments I made about Google Scholar in emails with the reporter.
Bohannon wrote to me on December 1, 2013
Dear Dr. Eisen-
I’m writing a news story for Science about Google Scholar. Have you continued using their article recommendation engine? (I saw your blog post about it from last year.)
(and then he wrote some details about what he was working on which I am not sure he would want me to post here and I have not asked so I am leaving them out)
I’d very much like to hear your thoughts on how Google Scholar has developed, and how well it works as a replacement for traditional library/proprietary/non-open literature databases.
cheers and thanks in advance,
John Bohannon
I wrote back, that same day (unusual for me)
Well, was just hacking around with Google Scholar this AM.
Have you dug into their new function – Scholar Library? I am playing around with it but have not quite figured it out. What I am hoping to do is to figure out how to get recommendations based on lists in the Library. Currently, the recommendation engine has one very very big limitation. It bases recommendations on one’s own publications. And if you are trying to move into a new area – well that is pretty useless.
So – some comments
1. I find the recommendation engine to be very very useful still. One of the best ways to find out about new papers. With the limitation mentioned above.
2. I use automated Google Scholar searches to find all sorts of papers of interest. This helps cover topics more broadly than the recommendation engine.
3. There are other recommendation systems out there – but I have not used them too much.
4. As for “free and open” – I don’t think I would use such terminology here. Yes, Google Scholar is free. But is it open? I don’t think so. For example, I am not sure if they publish / release all their code that works behind the scenes. And I am not sure how open the results are (not saying it is not open – I just don’t know).
5. The citation information is a wonderful tool – and it is great to have this information be freely available. I use it routinely for all sorts of purposes including getting around the massive limitations of IF. One issue however with GS is that it takes citations from ALL sorts of sources including non peer reviewed material and even material that people may not have been aware was even publicly available. So – citation counts are generally higher – sometimes much higher – in GS than with other metrics. I note – I put info for my Citations based on GS on my CV and various other places.
And this allows GS to be seriously gamed in terms of citation counts.
6. GS is still clunky in a few ways and I hope that Google puts more effort into it. It could become THE tool for academic scholarship searches and tracking but it has some bugs and minor annoyances still.
Just some quick thoughts. Let me know if you have any other questions.
Jonathan Eisen
He then wrote back with some questions. Again, I won’t share the whole email here at this time but I will share the specific questions he asked. And I then wrote back with some answers
Question:
** Care to share a recent example? Something nicely illustrates its usefulness.
Answer:
Question regarding my comment on other systems
Me: There are other recommendation systems out there – but I have not used them too much.
Bohannon: ** Are there? For example? I should take a gander.
Me: Mendeley has one – called recommended or something like that
Question regarding my comment on free vs. openBohannon: Right, good point. Free but not really open. Do you feel like this is a worrying limitation? Is it realistic to make it open? Or at least, more open?Me: Well, I am certainly not one to tell others how to run a business. So I am thankful for any free or open material released / produced by for profits. But there is a major worry here which is – if we do not know how the system works – we do not know if it is biased or how it can be gamed, etc. And if it is not fully open then if we invest in making use of it, Google could simply kill it at any time and we would have no source material to use for other purposes.Question regarding my comment on Impact FactorBohannon: What is an example of a massive limitation of IF that GS solves? And I wonder why GS can’t tell the difference between peer-reviewed and non-peer-reviewed sources. I’ll add that to questions below.Me: GS helps with article level metrics as opposed to journal level metrics like IF. I can look up citations to all my papers quickly. And I can track metrics like H index and I10 and others. IF – being a journal level metric – is not really that informative in my opinion (and that of many others)Question on other things GS could do:
Bohannon: What do you see as the most important things that need to be fixed before it could really take over?
Me:
1. Transparancy in how it works and it what they are planning
2. Make it open source
3. Ability to create reference collations easily (e.g., like Mendeley or Zotero or CiteULike or Endnote).
Questions for Google
Bohannon: * Any other questions you’d like Google to answer, or features to request?
Me:
Well many features to request.
1. Better hot linking of all authors of a paper. Right now they only seem to link the 1st author to their google scholar page.
2. Better handling of long author lists.
3. Better ability to upload collections exported from other tools.
And many more …
After this Bohannon then wrote me another email with additional questions which I answered, briefly
Bohannon: Questions I should have asked but forgot:Bohannon: When was the last time you exclusively used paper journals to find articles? (Ever?)Answer from me:never – or a very very very long time agosince I started using email / the web 20+ years ago I have tried to use electronic / digital searches to find papersBohannon: What electronic services did you use before GS?Answer from me:Pubmed searches of courseAnd pubmed had some automated email alerts that I used to useI also used lots of searches of journal web sitesAnd some journals offered automated searches tooThe best thing out there was probably “related articles” in PubmedBohannon: Have you switched entirely to GS?Answer from me:No – I still use pubmed searches quite a bit – partly because they are less cluttered than GS searchesI still occasionally search journal web sites but that is rareAnd I actually use straight google searches a lot
And then another question
Bohannon: Oh, and when did you start using GS? And when did it become your main search service?
(Sorry for the shotgun interrogation!)
Answer 1 from me:
heh – I have no idea …
Answer 2 from me:
I note – I think right now Twitter is the best source of information about new papers — far better than GS …
And I looked through my email and found that for a few years I used F1000 automated searches
And then in response to a follow up comment about Twitter from Bohannon I said
Yes, did not say Twitter was fun … but if you follow the right people, they can crowdsource for you all of the right literature better than GS
And then on Dec 6 Bohannon wrote me about visualizations
Hi Jonathan-
We’re sorting out some art for the article about Google Scholar. I’m thinking that the best option would be a cropped screen shot of one of your Google Scholar automatic article recommendations. Would you be OK with that?Do they come as an email or appear in browser? If email, you can just fwd it. If browser, could you take a screen shot and send it?The idea is to show people what GS article recommendations look like, using your own experience for a visual.
So I sent a few things including these


We had a few other discussions about related topics but I thought it might be useful to see that general gist of the discussion and some of my thoughts on Google Scholar in more detail. I note, at our meeting in February on the Future of Scholarly Publishing and Careers here at UC Davis Anurag Acharya from Google Scholar will be talking and will be on a discussion panel that will focus broadly on “metrics” for scholars so should be interesting.
Share this:

Some new posts by, well, me, of possible interest
So – I am trying to get some new project specific blogs up and running and have been writing some posts at those sites. And I thought I would just post a summary here of other posts I have written of possible interest.
- 12/12/13 UC Davis ADVANCE New paper on “Global gender disparities in science”
- 12/12/13 ICIS Blog Erik Kansa on “It’s the Neoliberalism, Stupid: Why Open Access / Data / Science is not Enough”
- 12/3/13 microBEnet blog Art and microbiology meet again but not in the way you might have expected
- 12/3/13 microBEnet blog New publications on ribosomal RNA tools (databases, software, etc)
- 11/30/13 ICIS Blog Wanted – low cost system for publishing an #OpenAccess journal
- 11/24/13 microBEnet blog Microbe video of the week: NPR Animation of the Human Microbiome
- 11/18/13 microBEnet blog Well, yuck, I guess: Fifty Shades of Grey goes viral – literally
Share this:
New paper on “Global gender disparities in science” (Crosspost from UC Davis ADVANCE Blog)
I am cross posting this from the UC Davis ADVANCE Blog where I posted it yesterday, since it is of relevance to this project and to the upcoming meeting we are organizing on “Publish or perish? The future of academic publishing and careers.”
There is an interesting new paper in Nature of interest. The paper is titled “Bibliometrics: Global gender disparities in science” and is by Vincent Larivière, Chaoqun Ni, Yves Gingras, Blaise Cronin & Cassidy R. Sugimoto. In the paper the authors report a detailed analysis three parameters:
- authorship of published scientific papers (which they use as a surrogate for research output)
- co-authorship on papers (which they use as a surrogate for collaboration)
- citations (which they use as a surrogate for scientific impact)
They then assigned gender to authors using multiple sources and examined the relationships between the 3 listed parameters and gender. And the findings are pretty striking.
I note – it is worth going to the Nature web cite for this article because some of the figures are interactive and one can click on different fields and change the plots.
The authors state – before digging into the details of their analysis “In our view, the scale of this study provides much-needed empirical evidence of the inequality that is still all too pervasive in science. It should serve as a call to action for the development of higher education and science policy.” A pretty strong statement that at least to me seems to be worth considering given their analysis.
Among their findings
- Globally men make up > 70% of the “fractionalized authorships” of scientific papers.
- Countries in S. America and E. Europe have somewhat better (on average) gender equity in authorship
- As shown previously, the gender ratio varies enormously between fields
- In terms of collaboration women tended to be more “domestically oriented” (i.e., focused on within country collaborations) than men.
- And the finding getting the most press — papers for which a woman had a prominent author position received fewer citations (on average) than those in which a man had such prominent position.
The authors then discuss the implications of their findings and make some recommendations for future actions. Among their conclusions (which I quote directly so as to not alter any implied meaning):
- “barriers to women in science remain widespread worldwide, despite more than a decade of policies aimed at levelling the playing field”
- “programmes fostering international collaboration for female researchers might help to level the playing field”
- “Any realistic policy to enhance women’s participation in the scientific workforce must take into account the variety of social, cultural, economic and political contexts in which students learn science and scientific work is performed”
This paper is definitely worth looking at in detail. And I note there is also a lot of supplemental material that might be worth downloading and playing around with. Data is critical for understanding the gender disparities in science and for planning and then testing ways to correct such disparities
Share this:
Erik Kansa on “It’s the Neoliberalism, Stupid: Why Open Access / Data / Science is not Enough”
Erik Kansa has an interesting post directly related to this ICIS project: Digging Digitally » It’s the Neoliberalism, Stupid: Why Open Access / Data / Science is not Enough. In his post Erik discusses some concerns he has with the “Openness” movement. Not that he is against openness – he is one of the biggest supporters of openness out there. But he has concerns with the need to go beyond just making material open. For example he writes
The problem is that the need for reform goes far deeper than simply making papers and data available under CC-By or CC-Zero. Exploitative publishing regimes are symptomatic of larger problems in the distribution of wealth and power. The concentration of wealth that warps so much of our political and economic life will inevitably warp the Open Movement toward unintended and unwanted outcomes.
Furthermore, he argues that we need more non-profit entities dedicated to the public good and leveraging openness. For example he writes.
For every PeerJ or Figshare (and these are ultimately just as dependent on continued public financing of research as any grant-driven project), we also need more innovative organizations like the Internet Archive, wholly dedicated to the public good and not the relentless pressure to commoditize everything (especially their patrons’ privacy).
This is definitely worth a look. And, if you want to hear more from Erik, come to the meeting we are organizing in February where he will be talking and will be on a discussion panel. Meeting registration information is here.
Share this:
Things I don’t understand episode 2000: Why in comparing humans & other animals the null hypothesis people always use (and thus try to disprove) is that humans ≠ animals
Well, this is something I just do not understand. I am sure others out there have thought about this more than I have. Just read this article: Considering the Humanity of Nonhumans – NYTimes.com discussing humans vs. non human animals. And there is this extensive discussion in there about whether animals have self awareness, and whether they deserve legal rights, and such. All very interesting I think.
But one part I do not understand. It is very clear that humans and other animals have many homologous features. It is very clear that humans are more closely related to some animals (e.g., primates) than to others. For many comparative studies of animals, if one wants to claim that some animal has a feature that is different from it’s close relatives, it is frequently up to the person proposing such a difference to disprove the null hypothesis that the close relatives are the same. This is the case when studying molecular processes, cell structures, physiology, genome structure, and so on.
Yet, there are a few biological features regarding humans for which it seems the null hypothesis everyone is forced to work with is the reverse. In these cases the null hypothesis is that we (i.e., humans) are unique and those who wish to claim that humans and other animals are similar / the same have to disprove the null hypothesis. This seems, well, awkward, at best. Basically, for some features – especially those that relate to intelligence and behavior – if one wants to claim that they are not unique one has to disprove the null. And yet, for all other features, the null hypothesis is that humans are not unique and those wanting to show uniqueness are forced to disprove this. On the one hand, I get this. There are many reasons why one might want to treat “humans are unique” in regards to intelligence and behavior – as the null hypothesis. But on the other hand – this seems exceptionally anthropocentric and has almost certainly prevented us from discovering and understanding certain behaviors and intelligence-related issues in non human animals. How do we as a community decided which null hypothesis to use for each phenotype?
Anyway – there it is. Something I do not understand.
Share this:
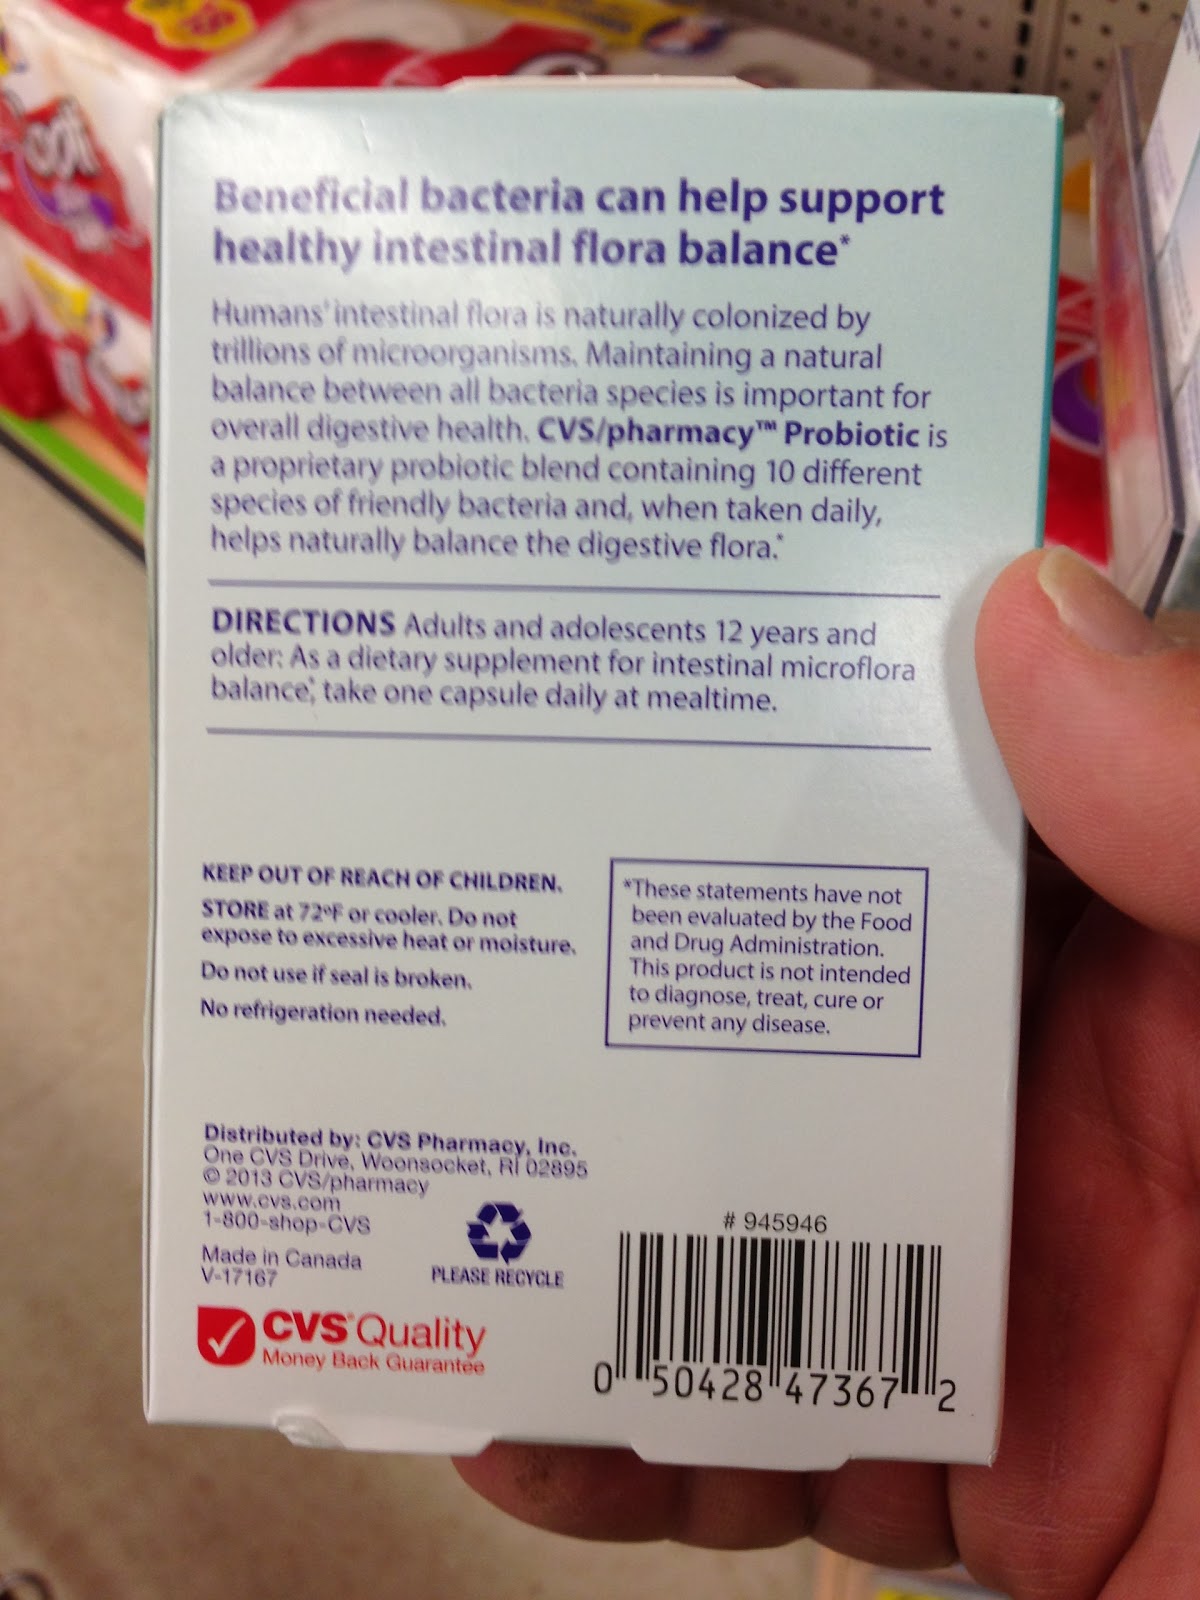
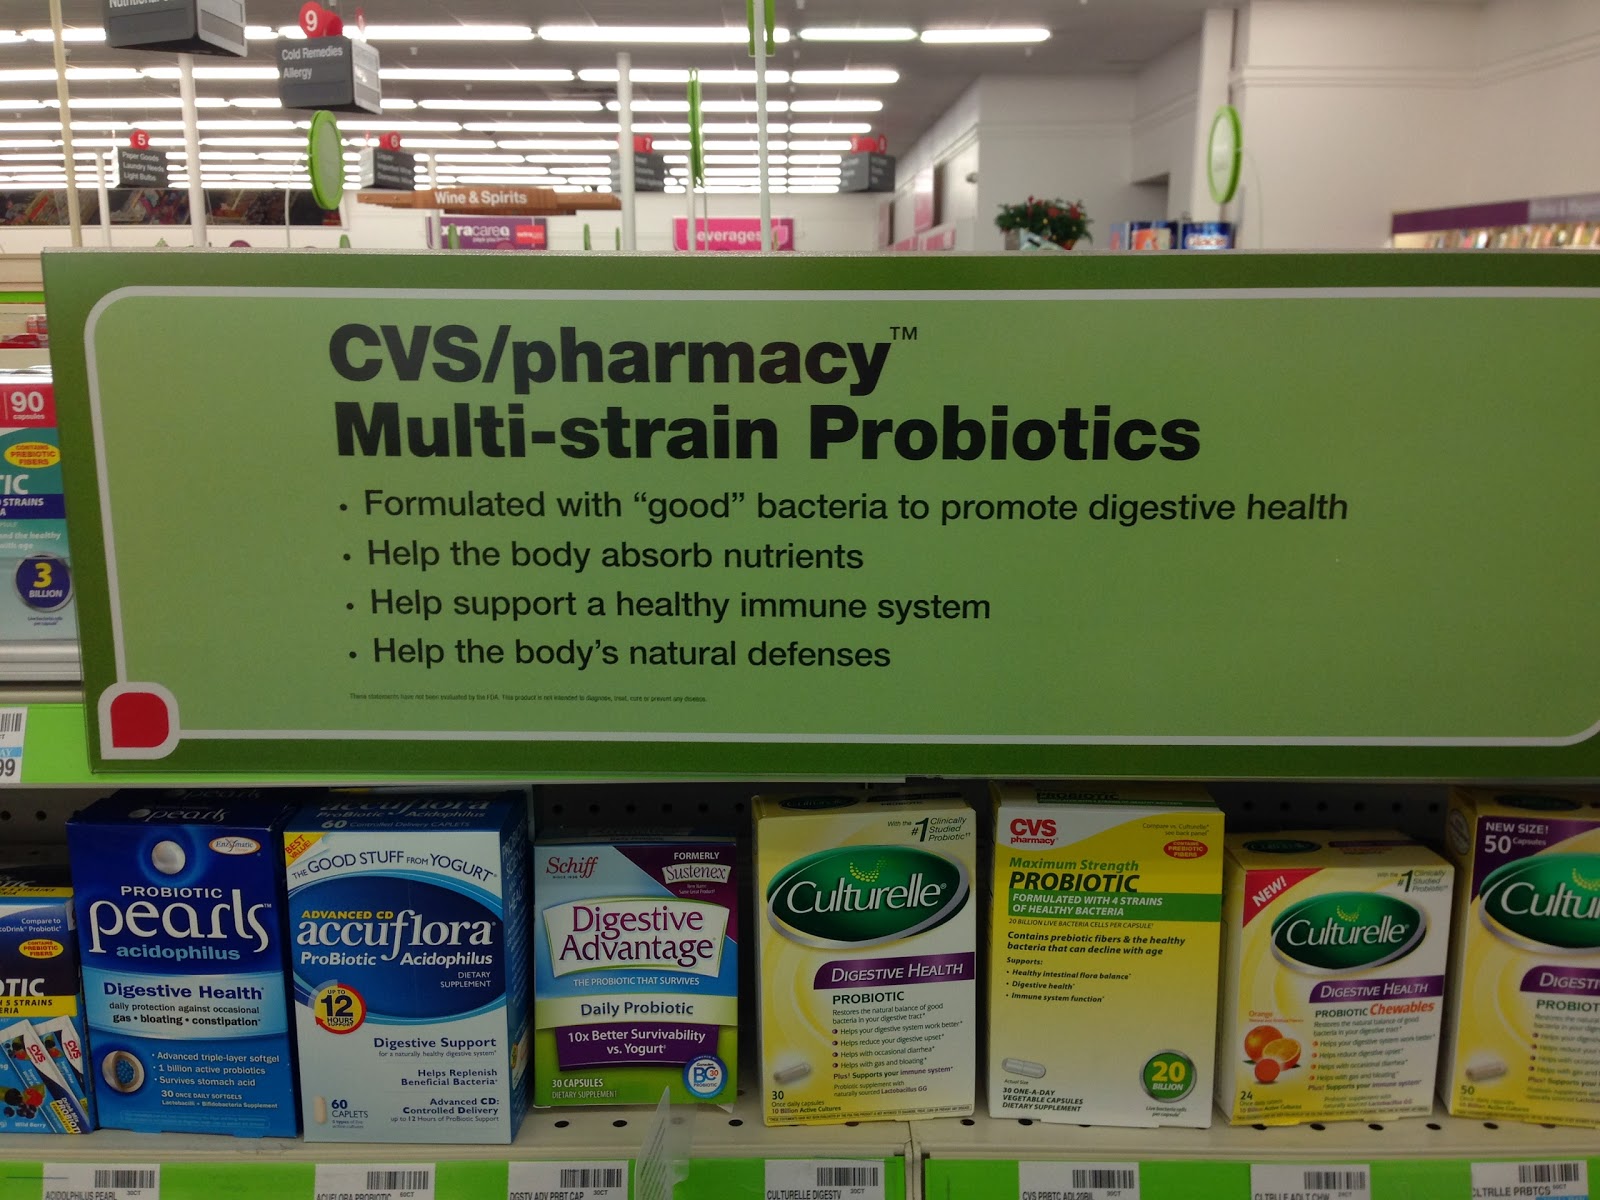
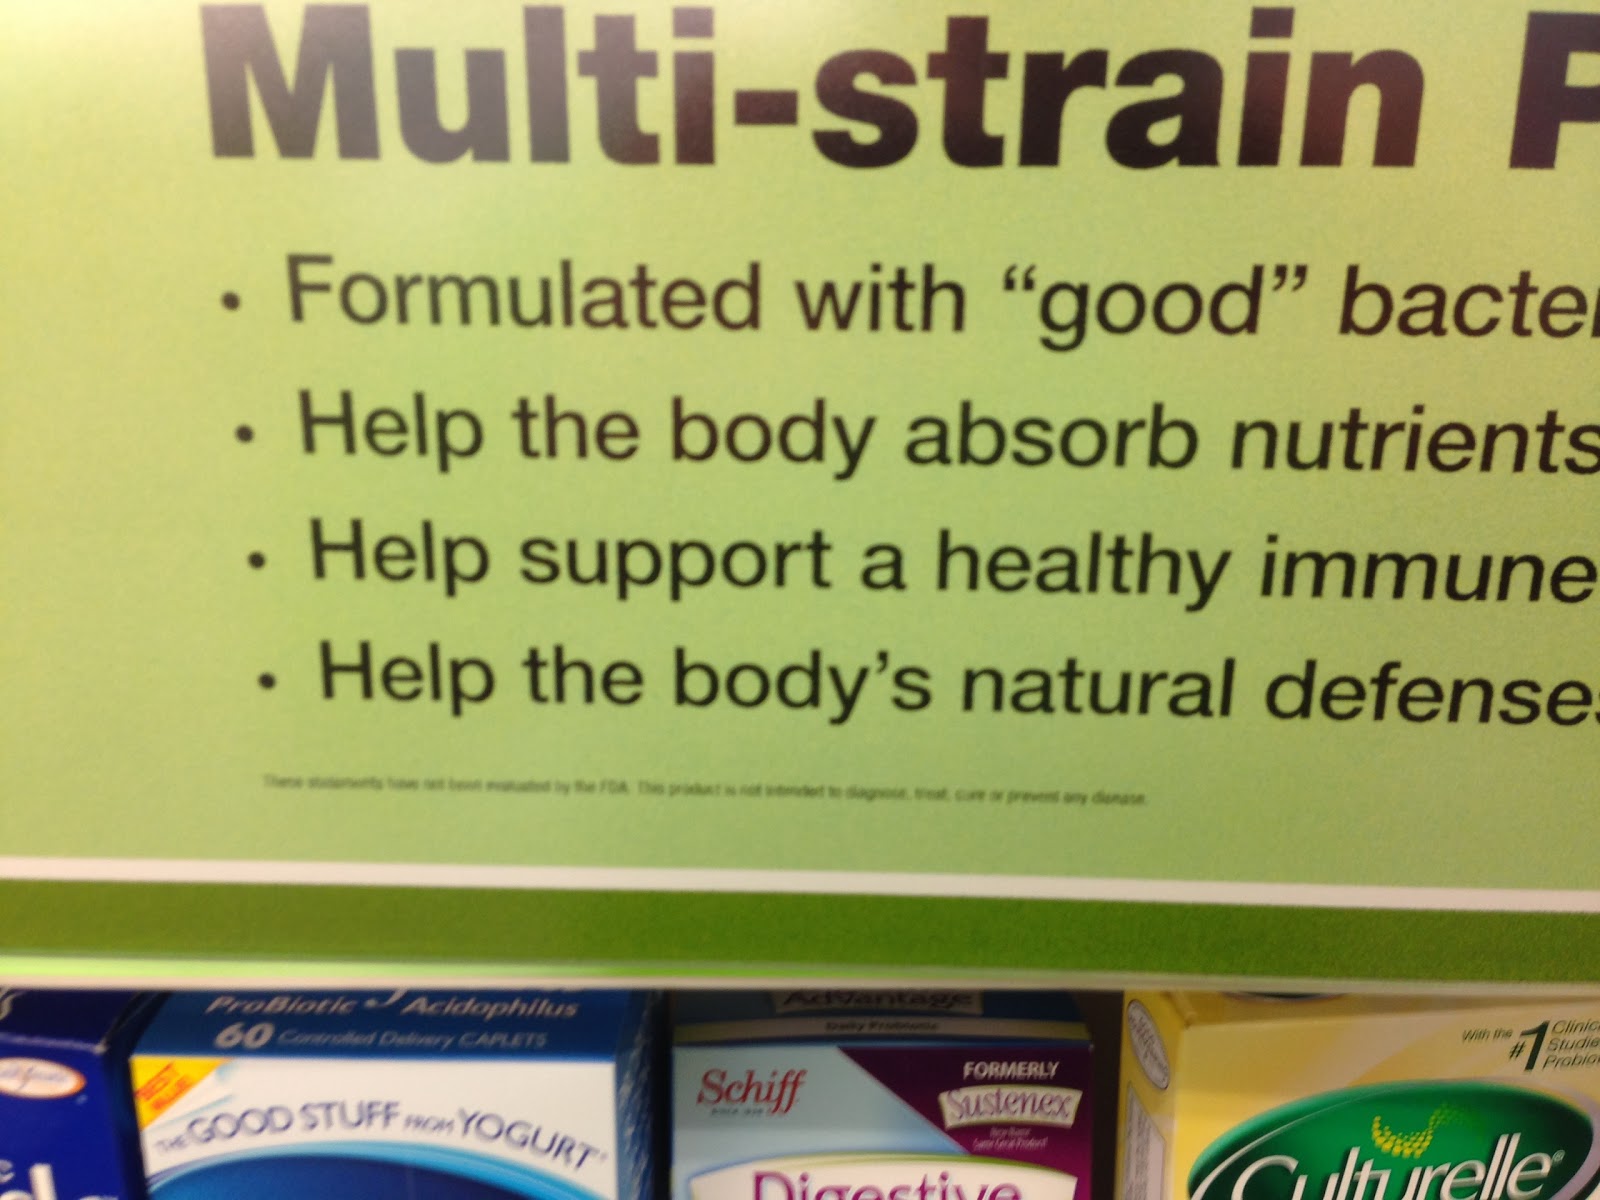
CVS marketing probiotics for everyone – even kids – & the disclaimers are barely visible
Just got back from the CVS drug store in Davis, CA and thought I would share some of the probiotic promotion they are doing. Not only are the probiotics now right next to the pharmacy counter (moving up in the world I suppose) but the probiotics are being marketed to all sorts of targeted groups. Alas, the science behind the claims here are dubious. And – sadly – CVS makes the disclaimer barely visible in many of the signs.


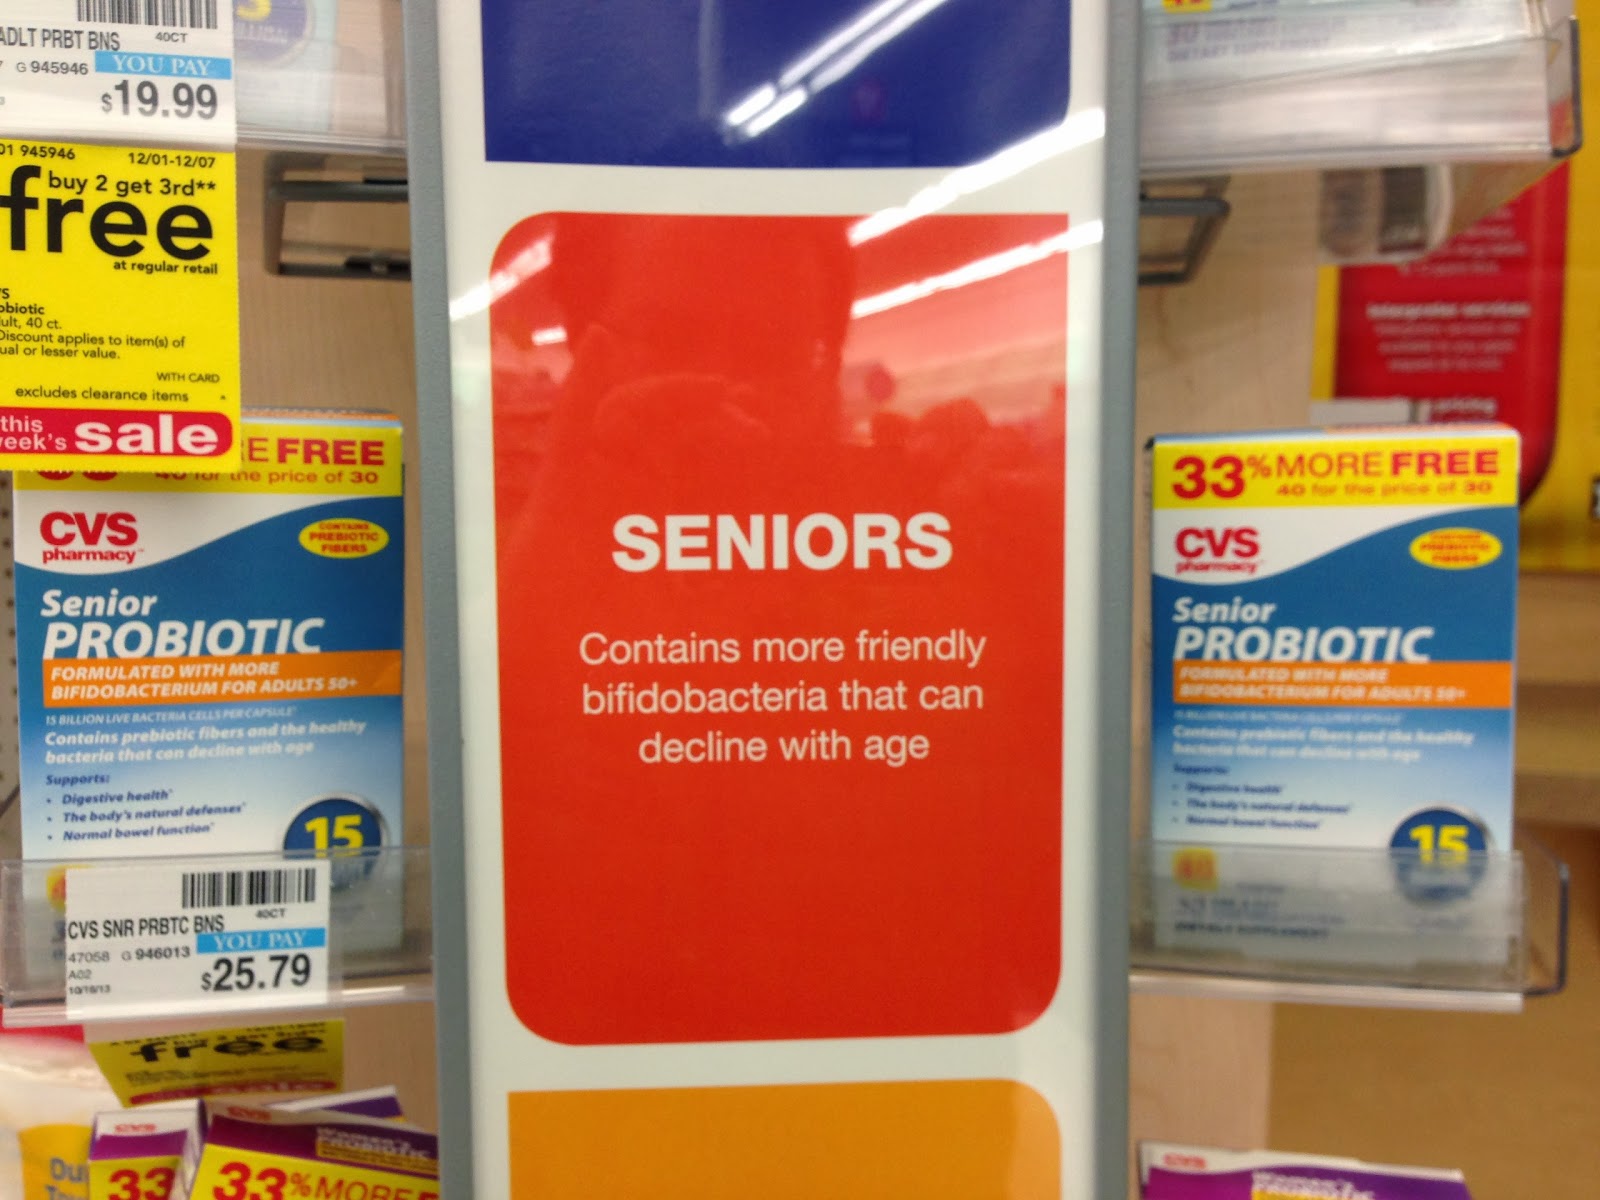


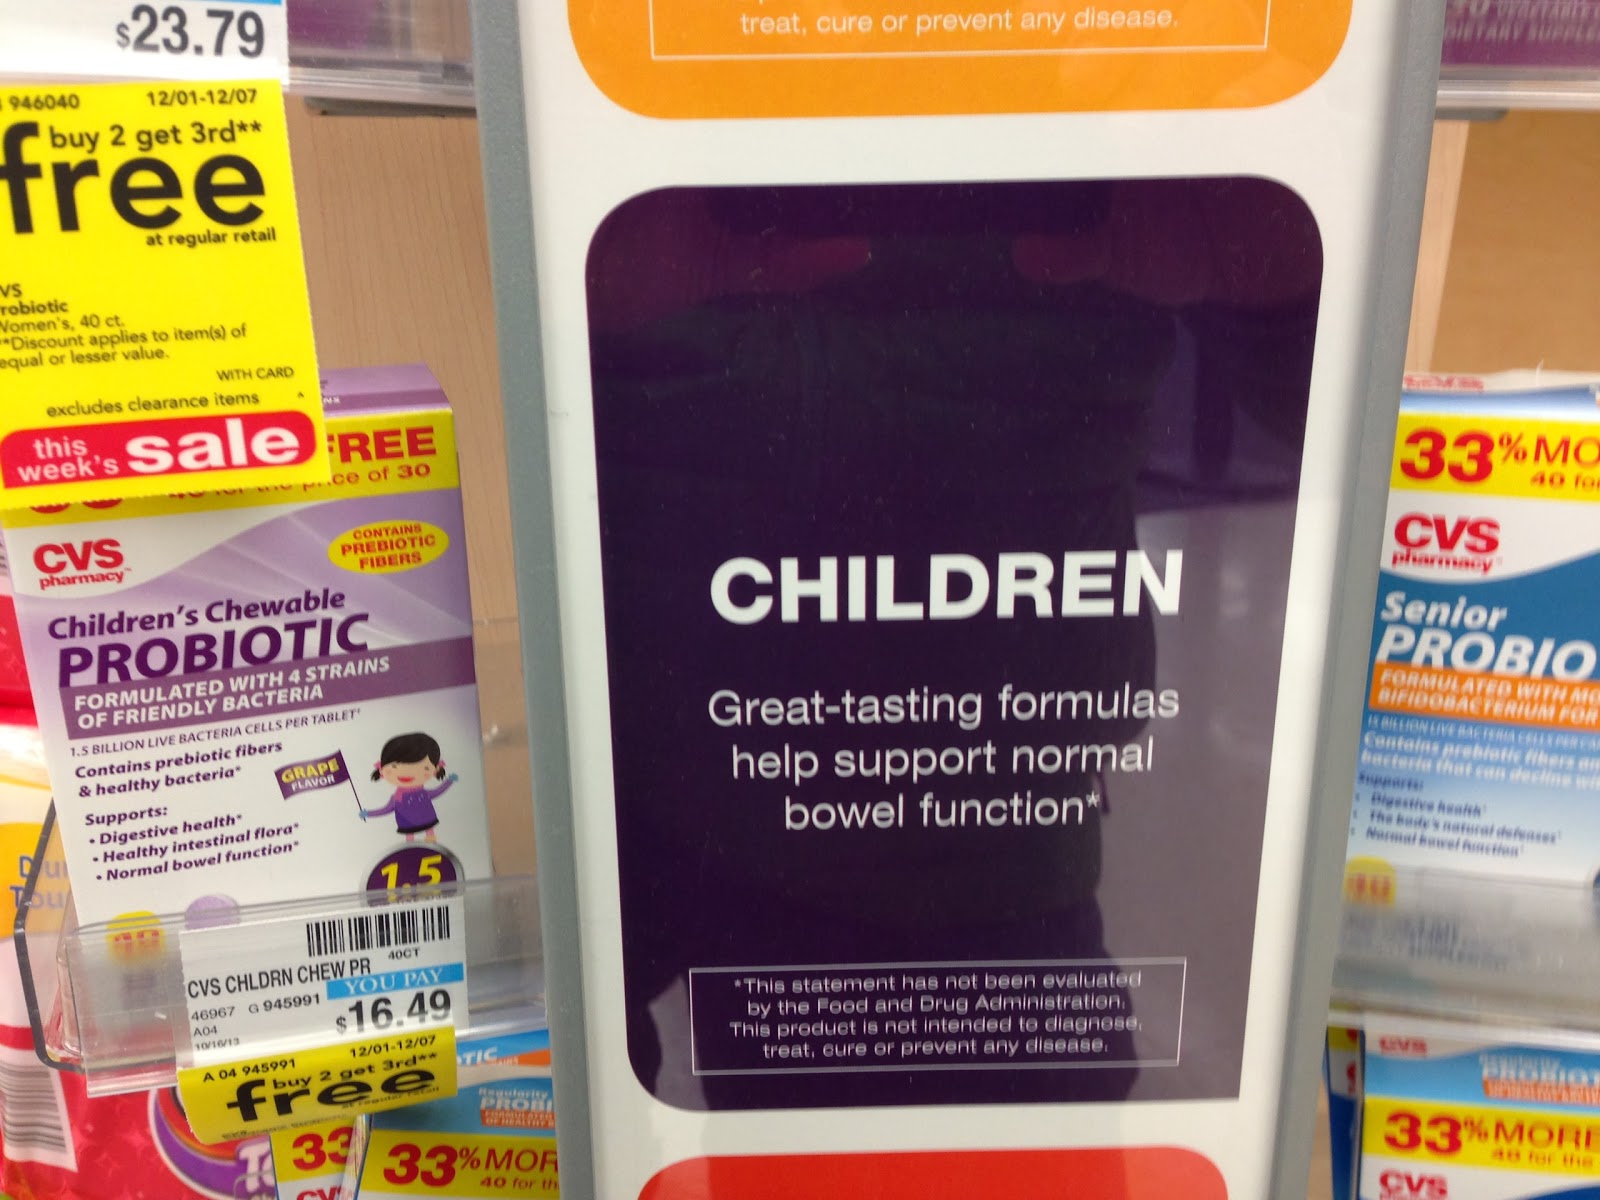
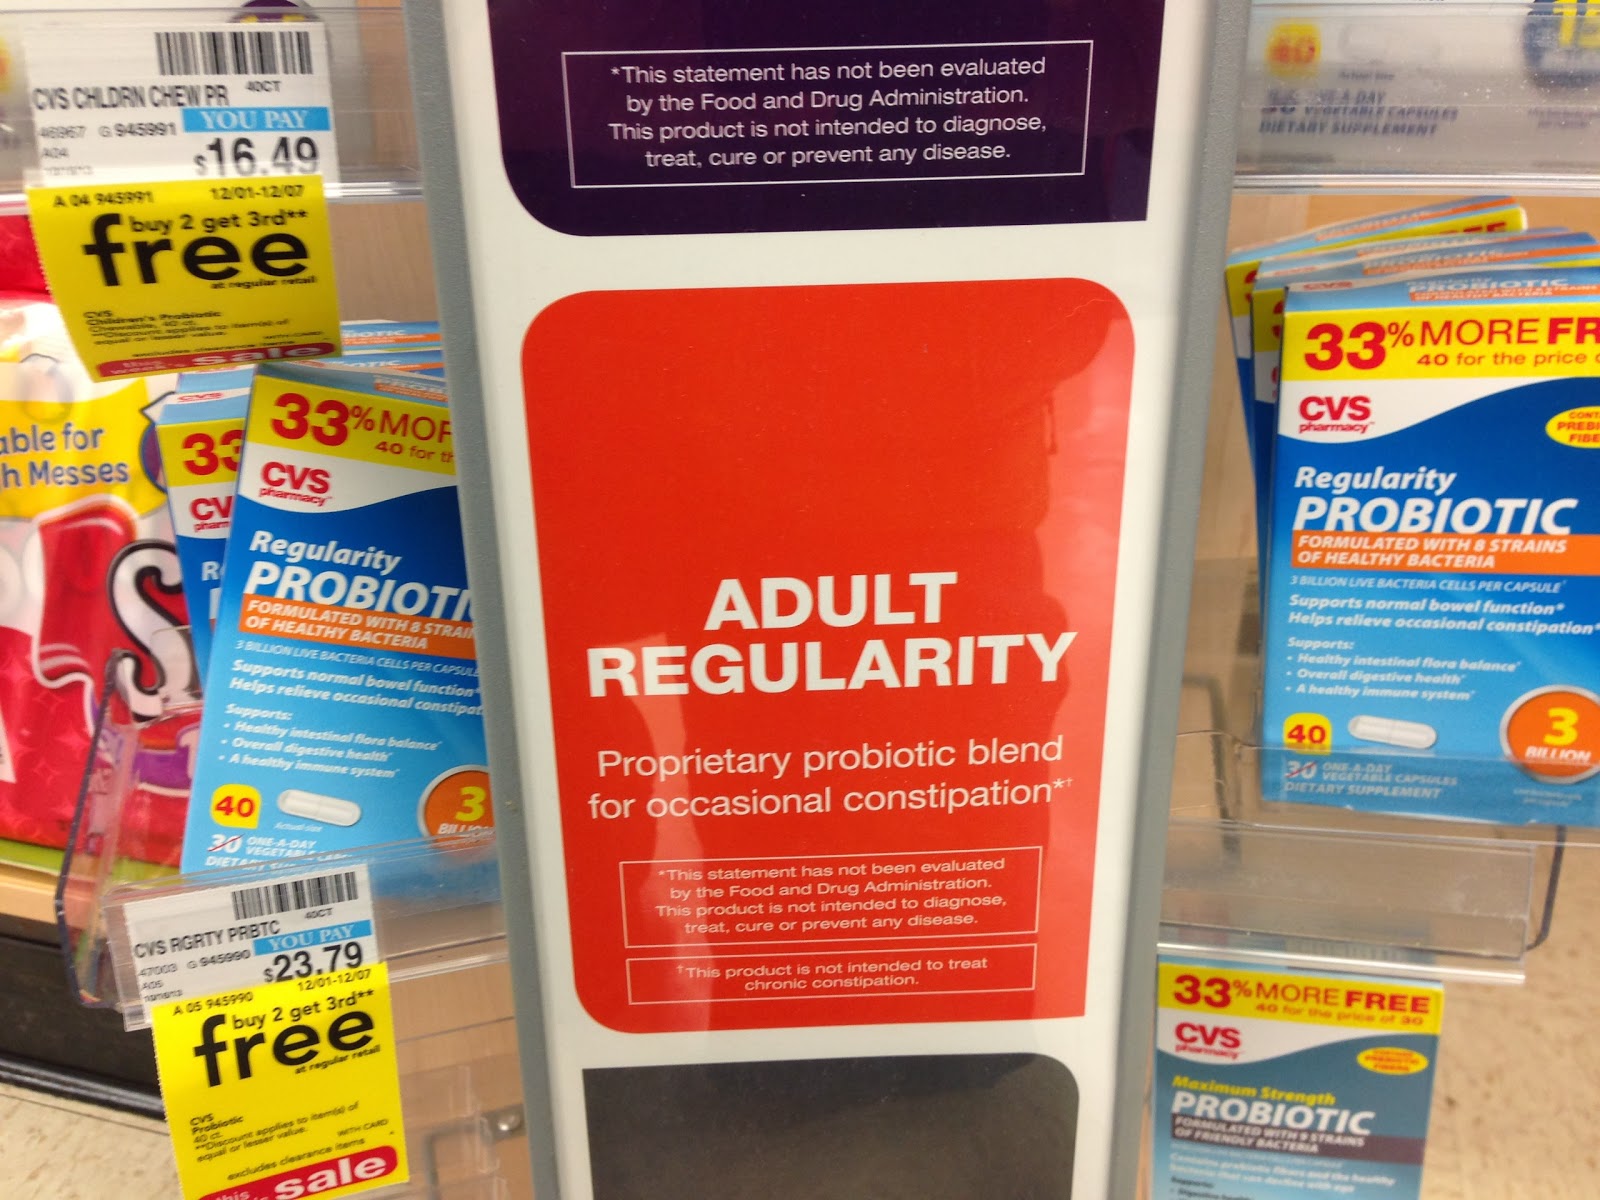
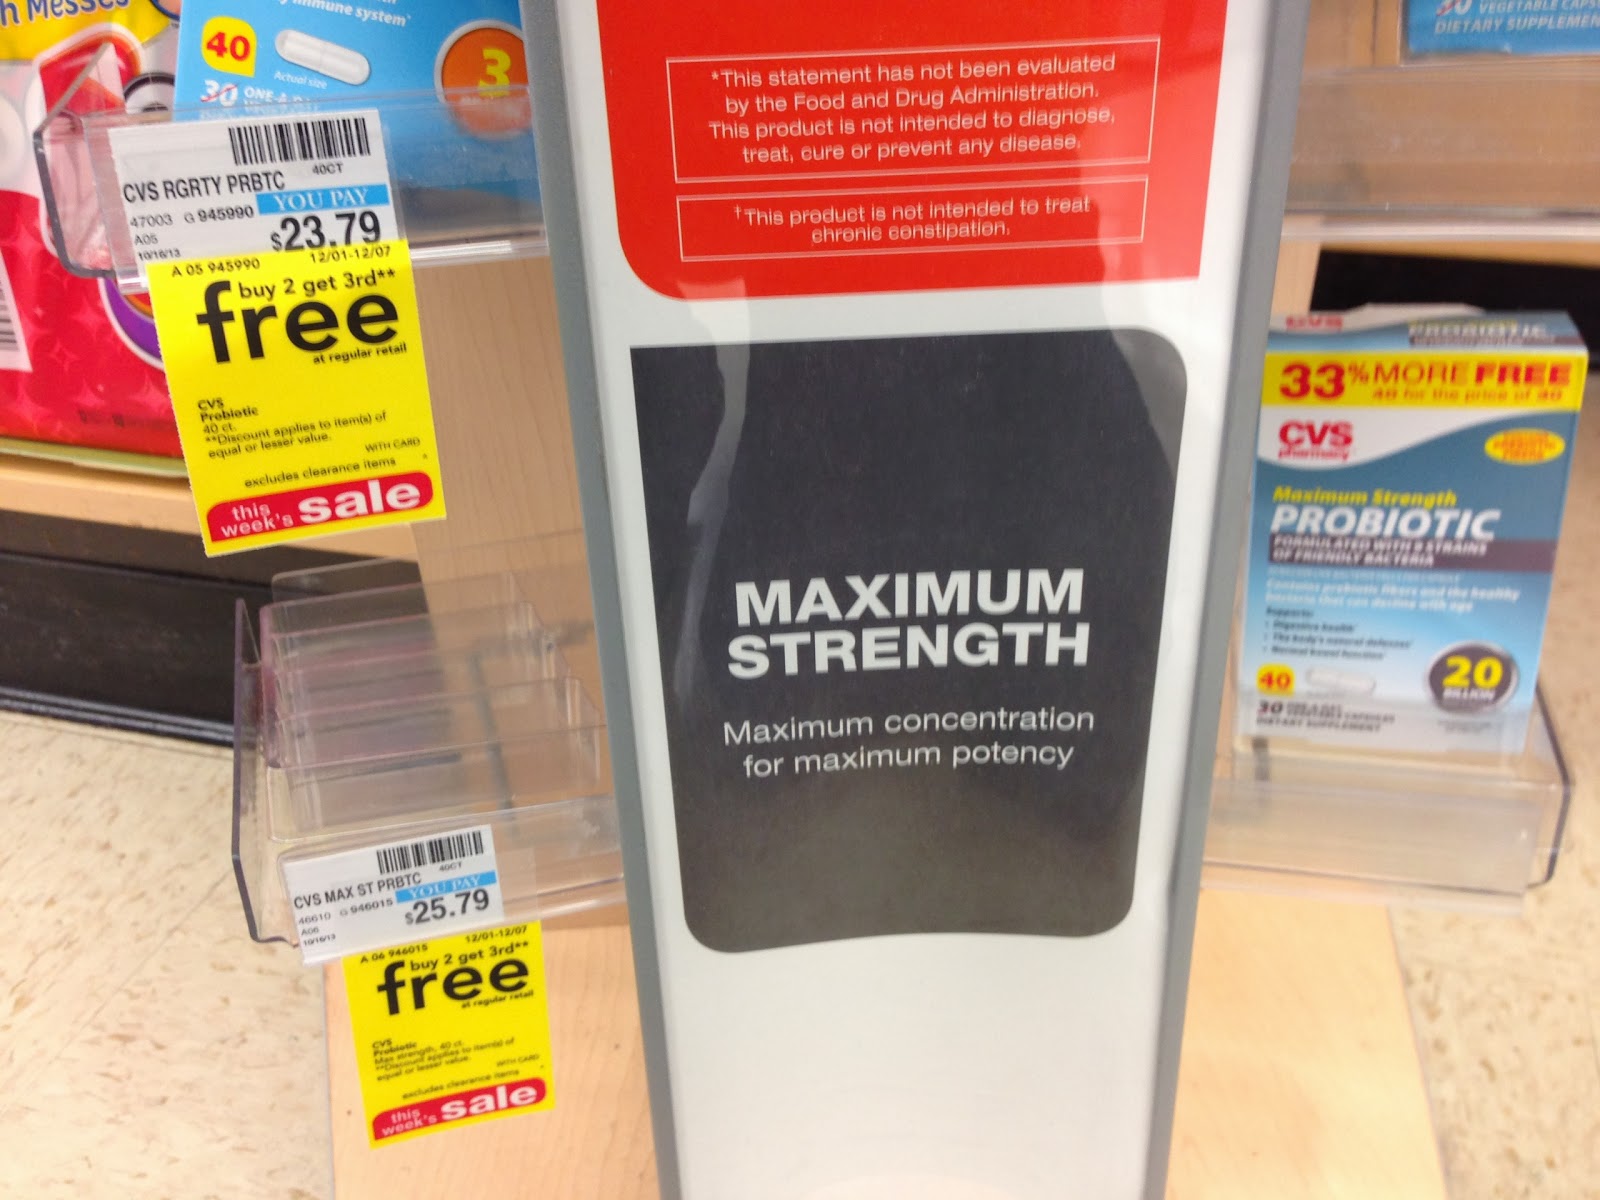




Share this:

Transitions in the CAMERA metagenomics database —
Just got this email announcement that I thought would be of interest:
Thank you for being a CAMERA user during its first phases of operation as a
resource for environmental genomics. During the past few years, CAMERA has
been able to offer a number of important community resources, including an
exceptionally well curated environmental genomic database, the ability for
researchers to deposit molecular sequence datasets with associated
environmental parameters (metadata), open access to computational resources
to enable metagenomic comparisons, educational resources and helpdesk
services. These efforts have been funded through the Gordon and Betty Moore
Foundation (GBMF) Marine Microbiology Initiative and the National Science
Foundation to serve the needs of the marine microbiology community and
other users.
As we announced earlier this year, CAMERA is undergoing a transition,
shifting from the Testing and Development phase of CAMERA 2.0 into multiple
entities that are supported by federal and foundation-funded projects for
developing and managing databases. Toward this end, we are re-prioritizing
access to the advanced data analysis capabilities of the system (see below)
while maintaining free and open access to CAMERA’s rich collection of
curated data and metadata. This will involve CAMERA being restructured into
a publicly accessible Data Distribution Center consisting of a simplified
website to enable streamlined access for downloading of sequence datasets
and associated metadata. This new interface will serve as an intuitively
accessible central repository, facilitating direct access to genomic,
metagenomic, transcriptomic, and metatransciptomic projects. Further, the
CAMERA 3.0 database will continue to grow and be maintained with the
inclusion of additional marine microbial datasets, such as the ~700 new
marine microbial eukaryote transcriptome datasets as part of the Marine
Microbial Eukaryote Transcriptome Sequencing Project
(marinemicroeukaryotes.org).
In the past, the CAMERA 2.0 compute resources, which include large-scale
BLAST capabilities and other workflow-enabled analysis capabilities, were
generously supported by the GBMF, the San Diego Supercomputer Center, the
NSF XSEDE program, and commercial Cloud computing resource providers,
Amazon and CODONiS. Due to increasing computational costs and the need for
scalability to larger, more complex datasets, it is now necessary for
CAMERA 3.0 to adopt a resource access model wherein projects will need to
identify sources of funding to cover their use of these advanced
capabilities. Starting January 1, 2014, CAMERA 3.0 will no longer offer the
use of computational resources to projects that cannot identify a source of
support for this component of CAMERA 3.0 services. As we shift to this new
usage model, we urge current users to download and save customized data
cart holdings and workflow analysis results before January 1, 2014.
While we are shifting to a restricted resource compute model, we will
continue to improve the capabilities of the system to expand the scientific
breadth of the data managed by CAMERA 3.0. For example, CAMERA 3.0 includes
fully functioning workflows for Illumina datasets, which can be made
available to those users who can identify a source of support for the
associated computational costs. In addition, CAMERA is actively seeking
resources to continue to take community data submissions. If you are now
collecting or have plans to collect data which you wish to deposit in
CAMERA, we urge you to contact us to help you to determine how to obtain
the resources required for these data to be archived and made available
through CAMERA.
Share this:
Email from #UCDavis on UC #OpenAccess Policy
Just got this email
Just got this email
On behalf of Provost Hexter and Academic Chair Nachtergaele, please find the attached letter regarding the UC Open Access policy. For your convenience and reference, the text of the letter is pasted below.
ACADEMIC SENATE AND ACADEMIC FEDERATION FACULTY
COUNCIL OF DEANS AND VICE CHANCELLORS
DEPARTMENT CHAIRS AND DIRECTORS
Dear Colleagues:
We are pleased to inform you that on July 24, 2013, the Academic Council voted to adopt an Open Access Policy for scholarly articles published by Senate faculty across the University of California system. An article deposit system to support the policy was released, on a pilot basis, at UCLA, UC Irvine and UC San Francisco on November 1, 2013, and will be officially rolled out at the other campuses on November 1, 2014, pending the outcome of the pilot.
The Open Access Policy allows faculty members to maintain legal control over their research articles while making their work much more widely available to the public. The policy does not require faculty to publish in open access journals, or to pay fees or charges to publish; instead it commits faculty to making a version of each article available publicly in an open access repository.
Faculty can take advantage of this right by using UC’s eScholarship digital repository via http://www.escholarship.org/ (or any other open access repository) to make a version of any article publicly and freely available worldwide. While it is expected that faculty at UCLA, UC Irvine and UCSF will make their articles freely available (via eScholarship or another OA Repository) effective immediately, faculty at the other 7 UC campuses are also free to begin depositing their articles now if they wish. Faculty authors may opt out of the policy for any given article, may delay the date of appearance of the article (“embargo” it), and may choose the terms of use that will be applied to each article (for example, whether it is for commercial or non-commercial reuse).
This policy has been under review by the Senate divisions and committees for two years and its implementation is a move of major significance. Policies like this one have been adopted by more than 175 universities but none as large, influential or productive as the University of California. The move signals to publishers that UC faculty want to see open access implemented on their own terms.
The California Digital Library and the campus libraries have developed a streamlined eScholarship deposit system and tools for obtaining waivers and embargoes to assist faculty in complying with the policy. The CDL has also contacted over 600 publishers to alert them to the policy and encourage their cooperation with its terms. Faculty on all campuses may receive questions about compliance from publishers and can consult the resources listed below (including an FAQ) for assistance.
Learn more about your rights and responsibilities under this policy at the UC Open Access Policy website.
Watch a 90-second video about the policy – and pass it on!
http://osc.universityofcalifornia.edu
Discover how easy it is to deposit your articles in eScholarship.
http://osc.universityofcalifornia.edu/open-access-policy/deposit/
Find out who to contact at your campus library for assistance.
http://osc.universityofcalifornia.edu/open-access-policy/oa-contacts/
Sincerely,
Ralph J. Hexter
Provost and Executive Vice Chancellor
Bruno Nachtergaele
Chair, Davis Division of the Academic Senate
Share this:
Mini journal club: staged phage attack of a humanizes microbiome of mouse
Doing another mini journal club here. Just got notified of this paper through some automated Google Scholar searches: Gnotobiotic mouse model of phage–bacterial host dynamics in the human gut
Full citation: Reyes, A., Wu, M., McNulty, N. P., Rohwer, F. L., & Gordon, J. I. (2013). Gnotobiotic mouse model of phage–bacterial host dynamics in the human gut. Proceedings of the National Academy of Sciences, 201319470.
The paper seems pretty fascinating at first glance. Basically they built on the Jeff Gordon germ free mouse model and introduced a defined set of cultured microbes that came from humans. And then they stages a phage attack on the system and monitored the response of the community to the phage attack.
 |
| Figure 1 from Reyes et al. |
They (of course) also did a control – in this case with heat killed phage. And they compared what happened to the live phage. I love this concept as they are able to control the microbial community and then test dynamics of how specific phage affect that community inside a living host. Very cool.


